
ASRock Radeon AI PRO R9700 Creator
4.4Editor score
32GB GDDR6 VRAM
Professional workstation drivers
Efficient blower cooling
Discover the top GPUs for LLM workloads comparing memory bandwidth, architecture, and performance for local inference and fine tuning.
Choosing the right graphics processing unit is critical for anyone serious about running local language models. Modern applications demand high memory capacity and fast bandwidth to handle complex tasks without bottlenecks.
We evaluated ten leading options based on architecture, VRAM size, and cooling efficiency. This guide compares consumer and workstation cards to help you find the perfect fit for your needs.
Each pick highlights specific strengths like AI acceleration or multi GPU support. Please note that availability and pricing fluctuate frequently so verify current listings before making a final purchase decision today.
4.4Editor score
4.6Editor score

4.3Editor score
This side-by-side comparison highlights the key specifications and capabilities of each graphics card to help you make an informed decision based on your specific workload requirements.


This card leads our list due to its powerful Blackwell architecture and high bandwidth memory. It excels at running large language models locally with minimal latency issues.
We may earn a commission when you buy through this link, at no additional cost to you.
The 16GB GDDR7 memory ensures smooth operation for most mid size models. WINDFORCE cooling keeps temperatures in check during extended inference sessions.
While it consumes significant power, the performance gains justify the cost for serious users. The PCIe 5.0 interface ensures future proof connectivity for your system.
Buy this if you need top tier performance without stepping up to enterprise hardware. It balances power and efficiency better than most competitors in this category.
The GDDR7 memory provides significantly faster data transfer rates than previous generations.
Multiple fans and heatsinks work together to maintain stable clock speeds.
We may earn a commission when you buy through this link, at no additional cost to you.
This workstation GPU offers an impressive 24GB of memory at a fraction of the cost of rivals. It is ideal for users on a tight budget needing large context windows.
We may earn a commission when you buy through this link, at no additional cost to you.
Intel Xe2-HPG architecture includes dedicated XMX engines for AI acceleration. This makes it capable of handling inference tasks efficiently without overheating.
Driver maturity is improving rapidly for this hardware. The blower style cooling is perfect for tight enclosures where space is limited.
Choose this if you need massive memory but have limited funds. It is a practical choice for entry level local AI development setups.
Twenty four gigabytes allows running larger models than typical consumer cards offer.
Low thermal design power reduces electricity costs and cooling requirements.
We may earn a commission when you buy through this link, at no additional cost to you.
This card targets professionals needing reliable performance for compute intensive workloads. Thirty two gigabytes of VRAM enables running complex models without swapping.
We may earn a commission when you buy through this link, at no additional cost to you.
AMD RDNA 4 includes dedicated AI accelerators for enhanced inference speeds. The blower cooling exhausts heat directly out of the chassis efficiently.
Professional drivers ensure stability during long training or inference runs. Build quality supports twenty four seven operation in server or workstation environments.
Invest in this for professional environments requiring sustained reliability. It bridges the gap between consumer and enterprise hardware effectively.
Enterprise grade thermal solutions prevent thermal throttling during continuous use.
Dedicated units speed up matrix operations common in LLM inference.
We may earn a commission when you buy through this link, at no additional cost to you.
This card offers excellent performance for gamers and AI enthusiasts alike. The 16GB memory handles many local models effectively without breaking the bank.
We may earn a commission when you buy through this link, at no additional cost to you.
WINDFORCE cooling with server grade gel ensures stable operation under load. High boost clocks provide the necessary compute power for complex tasks.
RGB lighting adds aesthetics but does not impact performance. The PCIe 5.0 interface ensures compatibility with modern platforms.
Pick this for a balanced build focusing on both gaming and AI. It delivers strong results for its price point.
Advanced thermal gel conducts heat away from the core quickly.
Next gen PCIe supports faster data transfer between CPU and GPU.
We may earn a commission when you buy through this link, at no additional cost to you.
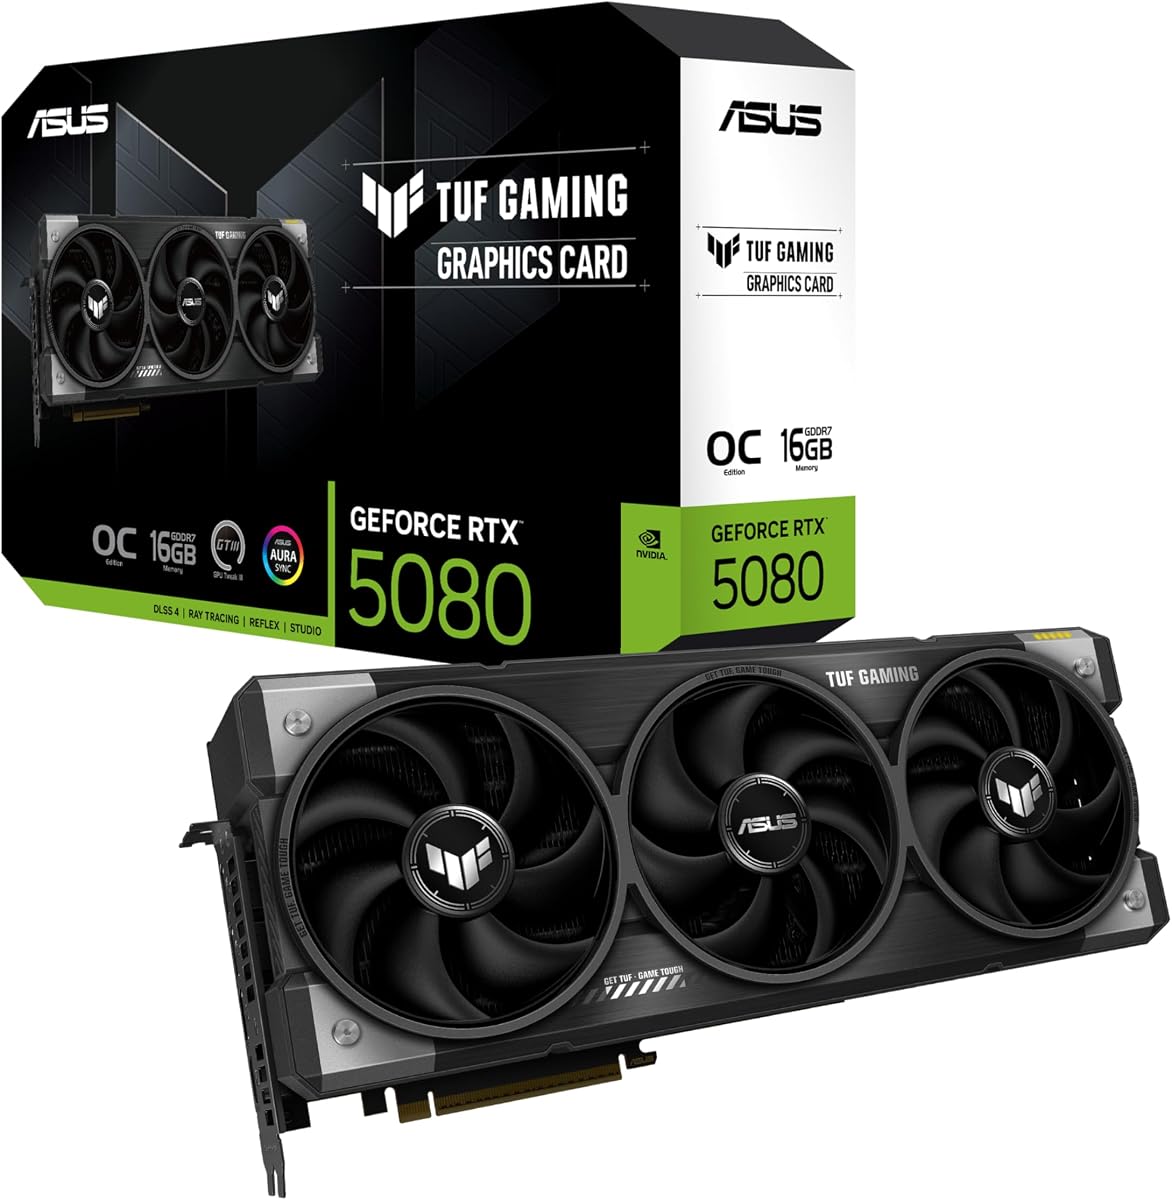
ASUS TUF series is known for ruggedness and reliability. This card handles intense workloads without failure thanks to military grade components.
We may earn a commission when you buy through this link, at no additional cost to you.
Phase change thermal pads outlast traditional paste and improve longevity. The Blackwell architecture powers efficient AI inference locally.
Protective PCB coating resists moisture and dust. This makes it suitable for varied environmental conditions.
Buy this if reliability is your top priority. It stands up to heavy use better than average cards.
Military grade capacitors ensure stable power delivery over time.
Special pads maintain consistent heat transfer under heavy loads.
We may earn a commission when you buy through this link, at no additional cost to you.
This card is specifically designed for running LLMs locally. Thirty two GB of memory removes VRAM bottlenecks for large models.
We may earn a commission when you buy through this link, at no additional cost to you.
128 AI Accelerators provide up to 1,531 TOPS for fast inference. Wave-pattern design cuts memory temperature significantly during long runs.
Dual ball fan bearings last twice as long as sleeve types. This ensures long term reliability for critical workloads.
Select this for dedicated AI infrastructure builds. It is purpose-built for modern generative pipelines.
Hardware acceleration tuned specifically for neural network inference.
Supports local clusters for increased total compute power.
We may earn a commission when you buy through this link, at no additional cost to you.
This card fits in smaller chassis without sacrificing too much power. Sixteen GB of memory is sufficient for many modern model sizes.
We may earn a commission when you buy through this link, at no additional cost to you.
Axial-tech fans move air efficiently with low noise. Dual BIOS allows switching between performance and quiet profiles easily.
Zero dB technology stops fans under light load. This keeps your workspace quiet during low utilization times.
Choose this for small form factor builds needing AI capability. It balances size and speed well.
Fans stop completely during idle to reduce noise pollution.
Two and a half slot design leaves room for other components.
We may earn a commission when you buy through this link, at no additional cost to you.
This accelerator is built for enterprise and HPC environments. Forty eight gigabytes of memory supports very large models comfortably.
We may earn a commission when you buy through this link, at no additional cost to you.
Designed for data centers, it prioritizes reliability over raw clock speed. Ideal for organizations scaling local AI infrastructure.
While expensive, the value comes from stability and memory capacity. It is not meant for typical desktop use.
Pick this for server deployments needing robust AI performance. It is a serious tool for serious work.
Hardware engineered for continuous operation in data center settings.
High capacity allows loading full models without offloading.
We may earn a commission when you buy through this link, at no additional cost to you.
This workstation card delivers 96GB of next-gen memory. It eliminates bottlenecks for massive models and multi-modal pipelines.
We may earn a commission when you buy through this link, at no additional cost to you.
Max-Q design ensures efficient power usage despite high performance. Five hundred twelve-bit bus width maximizes data throughput.
ECC memory prevents errors during long computations. This is vital for scientific and data science work.
Buy this if budget is secondary to capability. It is one of the most powerful consumer accessible cards.
ECC ensures data integrity during complex mathematical calculations.
Extreme bus width feeds data to cores as fast as possible.
We may earn a commission when you buy through this link, at no additional cost to you.
This professional workstation card offers unmatched capabilities for LLMs. Ninety six GB of memory allows full model hosting locally.
We may earn a commission when you buy through this link, at no additional cost to you.
Fifth generation Tensor cores deliver 3X performance gains. Universal MIG allows splitting resources for multiple users securely.
Double-flow cooling design optimizes airflow efficiency. It sustains peak performance even under heavy loads.
Select this for ultimate performance and isolation needs. It is the pinnacle of workstation GPU technology.
MIG allows safe sharing of GPU across different projects.
New Tensor cores accelerate matrix math for faster results.
We may earn a commission when you buy through this link, at no additional cost to you.
Selecting the right GPU requires understanding specific technical factors that impact AI performance directly.
VRAM size determines the maximum model size you can run locally. Models require roughly one byte of VRAM per parameter for inference. Large models like 70 billion parameters need at least 40GB to run efficiently without swapping.
Prioritize 24GB or higher if you plan to run large context windows or fine-tune models locally.
Bandwidth affects how fast the GPU can access stored data. Higher bandwidth means faster token generation during inference. Newer memory types like GDDR7 offer significantly higher throughput than GDDR6.
Look for cards with bandwidth above 500 GB/s to ensure smooth generation speeds.
Modern GPUs include dedicated tensor cores for AI workloads. These cores handle matrix multiplication far faster than standard shaders. Check for compatibility with frameworks like PyTorch or TensorFlow.
Ensure the architecture supports current AI libraries to avoid compatibility issues.
High performance GPUs consume significant electricity. You need a compatible power supply with sufficient wattage and connectors. Verify your chassis can dissipate the heat generated effectively.
Choose a PSU with 200W headroom to account for power spikes safely.
Sustained workloads generate heat that can throttle performance. Blower coolers exhaust heat outside the case which is vital for multi-GPU setups. Open air coolers provide better single card cooling.
Select a cooling solution that matches your chassis airflow and slot density.
Driver maturity is critical for stability in AI workflows. Some cards offer optimized libraries that improve performance significantly. Check community support for your chosen framework.
Opt for brands with strong driver support to minimize configuration headaches.
Modern GPUs can be extremely long and thick. Verify your case supports the length and width before purchase. Clearance for cables and PCIe slots is also important.
Measure your case interior to prevent build issues after purchasing.
Model sizes are growing rapidly requiring more resources. Cards with PCIe Gen 5 offer higher bandwidth for future CPUs. Investing in more VRAM now prevents premature upgrades.
Choose specs that exceed current needs to accommodate upcoming model releases.
Install the latest drivers from the manufacturer to ensure stability. Verify compatibility with your AI software stack before running heavy loads.
Monitor temperatures during long inference sessions using system tools. If the GPU throttles, adjust fan curves to improve cooling efficiency.
Keep your system clean of dust to maintain airflow. Regularly clean fans and vents to prevent overheating issues over time.
For most models you should aim for at least 16GB of VRAM. Larger models like 70B parameters require 40GB or more to run efficiently without swapping to system RAM.
Yes many setups support multi GPU scaling for increased capacity. However ensure the software you use supports distributed inference across cards properly.
GDDR7 offers higher bandwidth and lower latency than GDDR6. This results in faster data transfer rates which directly speeds up token generation.
Error correcting memory is vital for scientific computing and long runs. For general inference it is less critical but prevents silent data corruption in important tasks.
Check the card manufacturer for TDP and connector requirements. Most high-end cards require 850W or more with 12VHPWR connectors included.
Download the latest drivers from NVIDIA or AMD websites. Ensure CUDA or ROCm support is enabled for your specific software stack.
We highlighted ten options ranging from budget friendly consumer cards to professional workstation solutions. The top picks balance memory size performance and reliability effectively.
Prioritize VRAM capacity and bandwidth for your specific model requirements. Choose based on your workload whether it is training or inference focused.
Always check current pricing and stock before finalizing your order. Prices fluctuate often so verify the latest deals before purchasing.